Bubble Sensor Manufacturer Selection Guide for Reliable Fluid Detection
2026-10-13
Every bubble tells a story—especially when it slips through a fluid line undetected. In medical, industrial, and life science systems, even a micro-sized air pocket can distort readings, damage equipment, or compromise patient safety. Yet choosing a bubble sensor manufacturer isn’t just about sensitivity specs; it’s about trusting a partner whose sensors perform consistently when your process can’t afford a second chance. This guide breaks down what separates dependable suppliers from the rest, and why teams increasingly look to Siansonic for fluid detection that holds up under real-world pressure.
Zeroing In on Sensor Accuracy That Holds Up Over Time
Most sensors leave the factory with impressive spec sheets, but the real test begins after months of thermal cycling, vibration, and exposure to whatever the environment throws at them. Drift doesn't announce itself with a warning light—it quietly eats away at baseline readings until decisions built on that data start to miss. Accuracy that holds up over time isn't a single calibration event; it's a design philosophy that treats every component as a potential source of slow-moving error.
The trick is to stop chasing perfect initial readings and start engineering for predictable behavior. That means picking reference elements that age gracefully, building in redundant measurement paths so one drifting channel gets flagged early, and writing compensation algorithms that learn from the sensor's own history rather than relying on fixed offsets. Some of the most reliable long-term instruments aren't the ones with the highest resolution—they're the ones that tell you when they're no longer sure of themselves.
Field validation separates the claims from the reality. Accelerated life testing helps, but there's no substitute for pulling units after two years in a dusty compressor room or a salt-sprayed rooftop and comparing their output to a fresh traceable standard. The sensors that survive that scrutiny tend to share a boring quality: they were overbuilt for normal conditions, characterized across the full operating range, and designed so that recalibration doesn't require a PhD—or a week of downtime.
Materials That Won't Quit When Fluids Get Aggressive
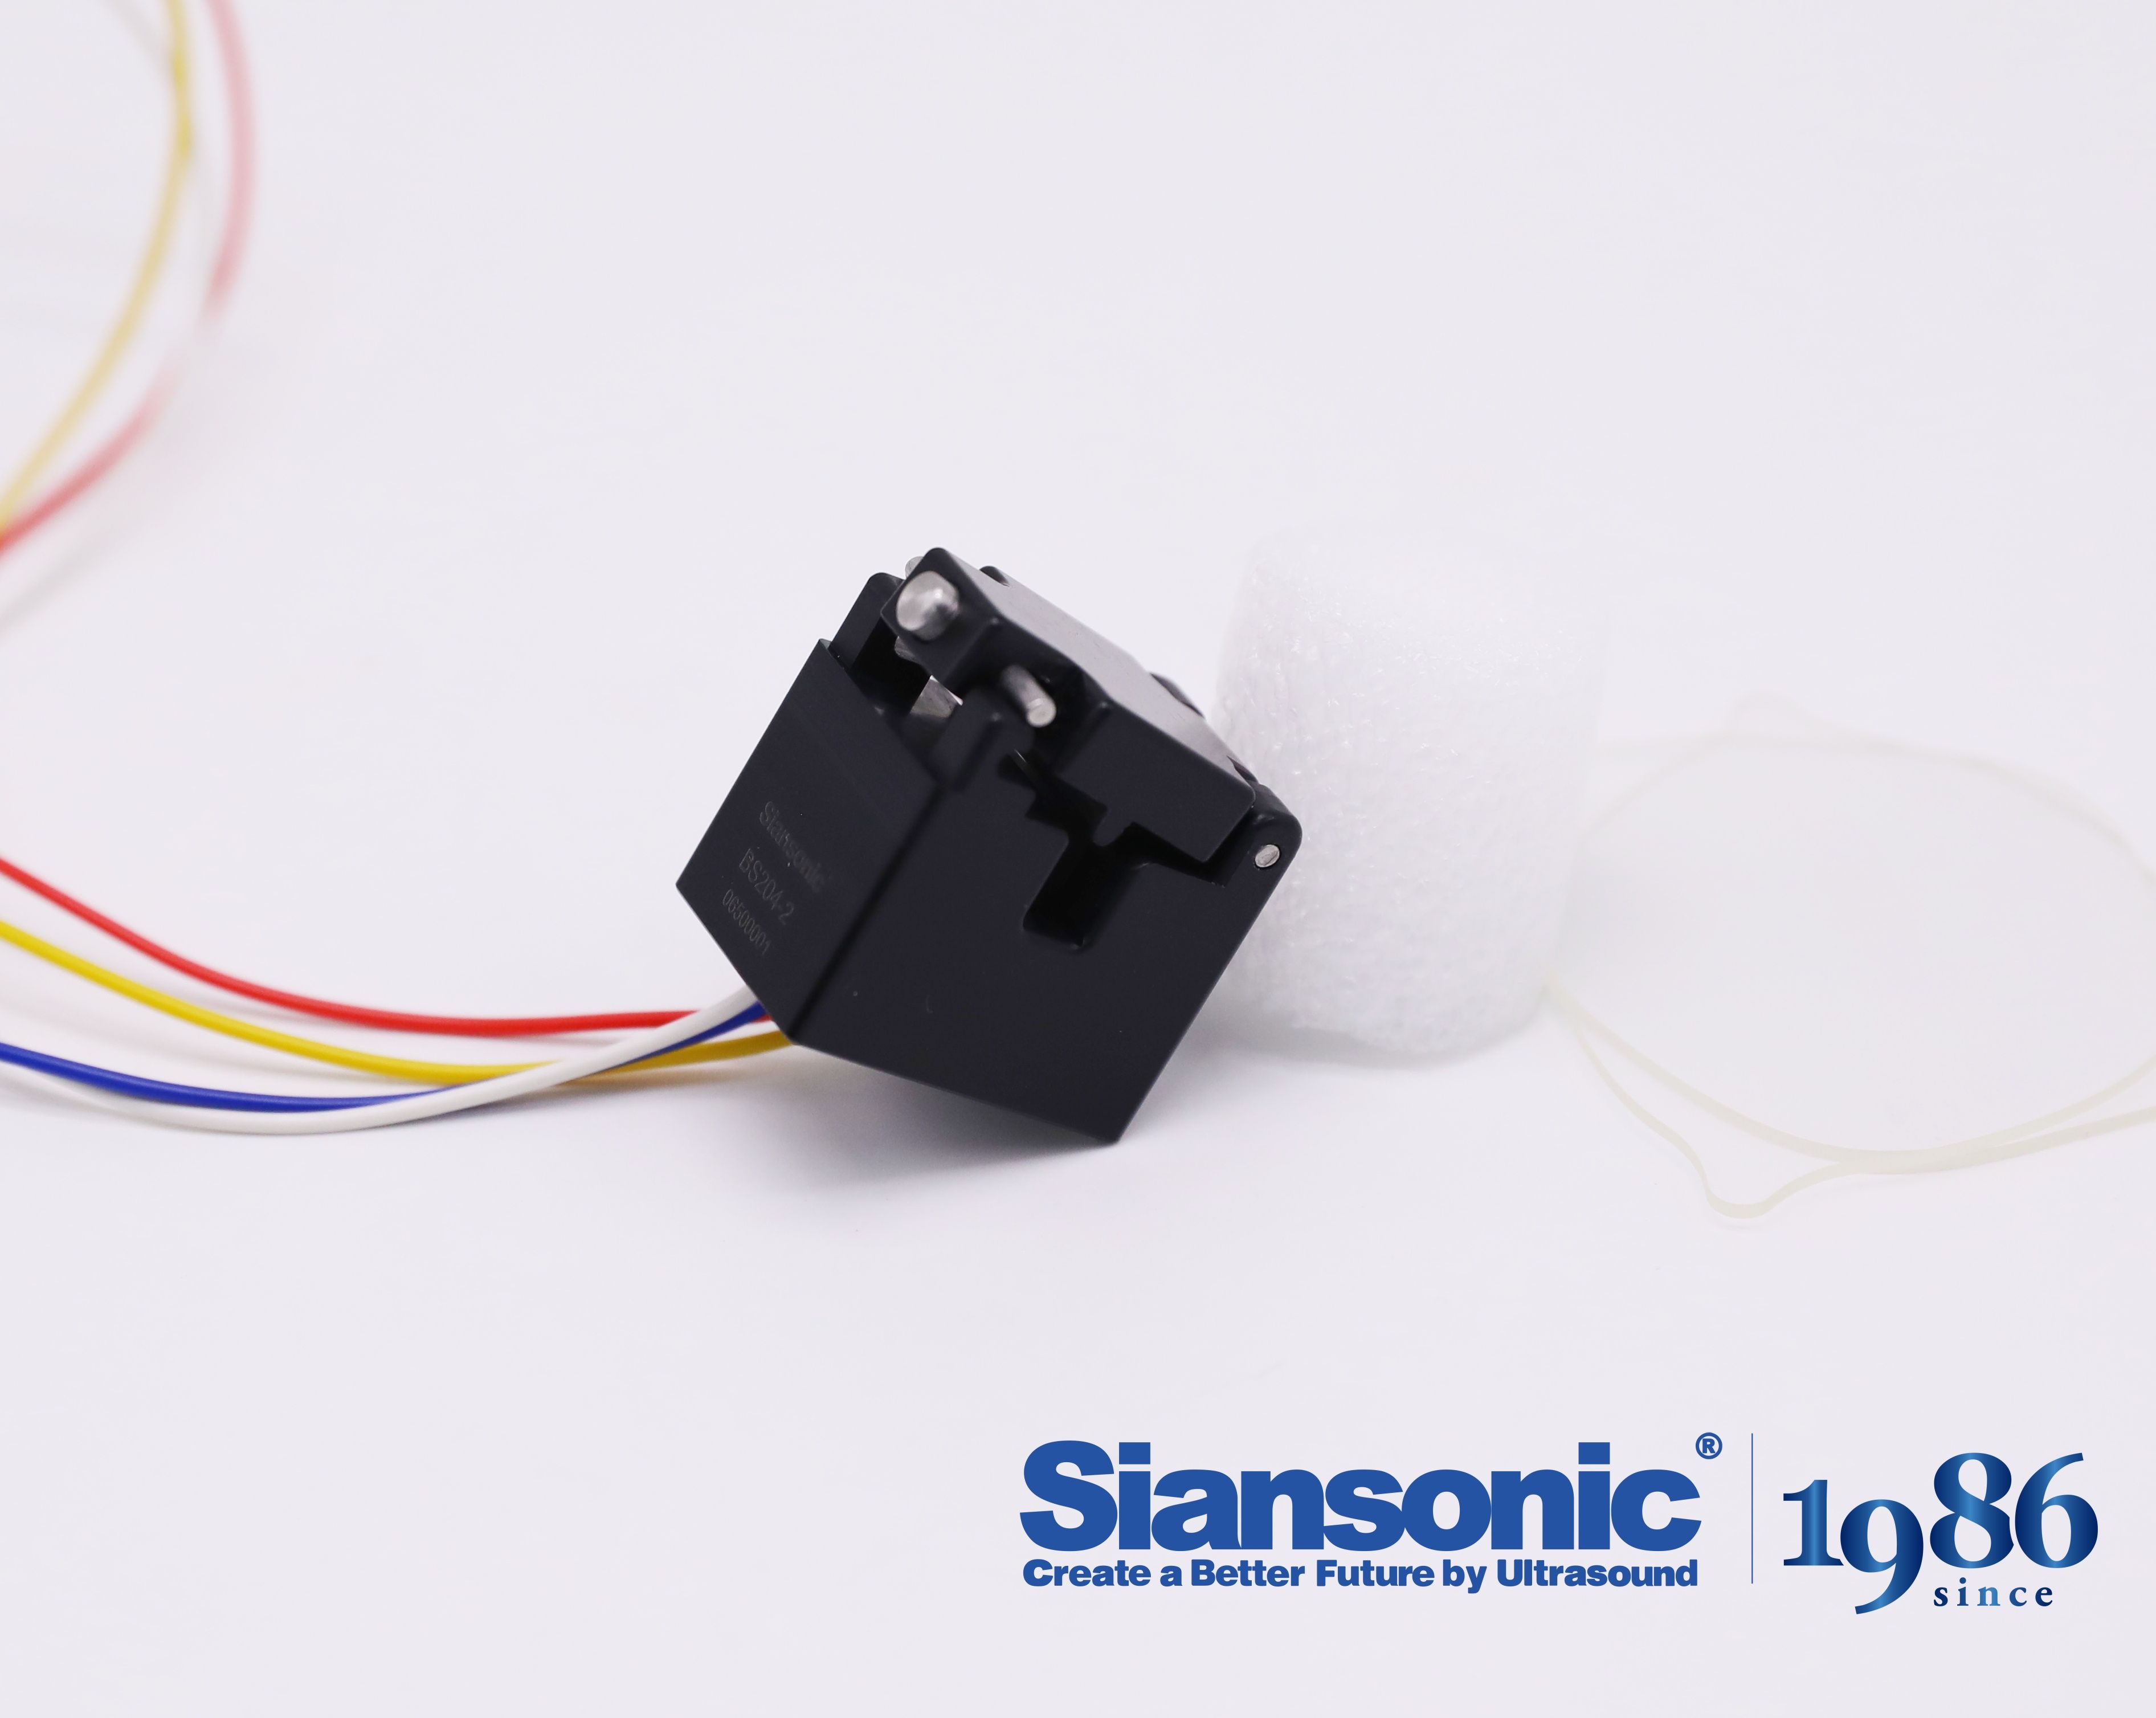
Aggressive fluids destroy ordinary materials in predictable ways: hot sulfuric acid eats through stainless steel piping, abrasive slurries erode pump impellers, and supercritical carbon dioxide embrittles standard elastomers. Engineers who deal with these conditions quickly learn that survival is rarely about raw hardness or thickness alone. It hinges on subtle chemistry—the ability of a metal to form a tenacious passive oxide layer, or a polymer to resist chain scission—and on microstructure designed to deflect or absorb damage before it propagates.
The real workhorses in harsh fluid service are often specialized alloys and ceramics. Nickel-based superalloys like Hastelloy C-276 hold up in chloride-rich brines that would pit standard stainless steel within days. Silicon carbide, nearly as hard as diamond, combines acid inertness with exceptional resistance to particle erosion, making it a favorite for mechanical seals and slurry-handling components. In the polymer world, fluoroelastomers such as Viton keep their flexibility when solvents and hot oils attack, while perfluoroelastomers extend that range even further into aggressive chemical environments.
Beyond bulk materials, surface engineering and hybrid designs offer another layer of resilience. Diamond-like carbon coatings, applied by plasma-assisted deposition, reduce friction and protect underlying metals from both corrosion and wear in downhole tools. In deep-well drilling, tungsten carbide inserts are brazed onto steel bit bodies to survive the twin assault of high-pressure abrasive mud and hydrogen sulfide gas. These solutions don't just resist degradation—they embody a practical philosophy: match the material's failure mode to the specific aggression of the fluid, then add redundancy where uncertainty remains.
Reading Fluid Signals Without False Alarms
Interpreting fluid signals in real time demands a careful separation between genuine process shifts and the chatter of everyday measurement noise. Depending on the sensor, even a stable flow can produce rapid fluctuations from turbulence, pump harmonics, or electrical interference. Treating every spike as a meaningful event leads to operator fatigue and ignored alarms. The better approach is to first establish what a quiet baseline looks like for that specific line, including normal vibration patterns and minor pressure ripples, before flagging anything out of the ordinary.
One practical way to reduce false alarms is to delay the trigger slightly while evaluating persistence. A single excursion past a fixed limit often means nothing, but a sustained departure lasting several seconds or multiple consecutive samples above the same threshold usually indicates a real change. Pairing this time-based confirmation with context such as valve position, pump start-up sequences, or known batch transitions adds a layer of logic that static alarm settings cannot provide. This keeps the operator's attention on events that actually demand a response.
Finally, the alarm threshold itself should not be a fixed number chiseled in place during commissioning. Fluid systems drift as filters load, impellers wear, and ambient temperatures swing. A threshold that was reasonable in January may be too tight in July, generating nuisance alarms. Periodically reviewing and re-baselining normal operation, or using adaptive limits that track slow changes, keeps the system sensitive to true upsets while rejecting the everyday variability that never posed a threat.
Custom Builds That Fit More Than a Datasheet
Most off-the-shelf hardware forces you to compromise somewhere—power envelope, footprint, connector placement, or that one peripheral you always end up bolting on as an afterthought. A custom build starts from a different question: what does this actually need to do in the field, on the bench, or inside a product that has to ship next quarter? When the engineering conversation moves past a datasheet, we can size power stages for real thermal conditions, move mounting points to match your enclosure, or pre-wire the exact I/O so your firmware team doesn’t spend a week chasing a level shifter.
That extra fit shows up in the details datasheets never capture—cable routing that survives vibration, silkscreen labels your technicians actually recognize, and a boot sequence that doesn’t require a logic analyzer to debug. We’ve built boards where the custom part wasn’t exotic silicon but the way the board sat flush in a housing with only 2.1 mm of clearance, or the way a display connector landed exactly where a user’s thumb rests. These are not bullet points on a comparison table; they’re the reasons a prototype turns into a production run without a redesign.
From Prototype to Production Without the Runaround
The gap between a working prototype and a production-ready system often hides in the least glamorous places: messy handoffs, undocumented assumptions, and the slow erosion of momentum. When the team that built the proof of concept isn't the same one responsible for deployment, every missing detail becomes a meeting. The fix isn't more process—it's fewer, sharper transition points. Write down what the prototype actually does, what it ignores, and where the shortcuts are, then hand that list to the people who will inherit the code. That single act removes most of the runaround before it starts.
A common stall happens when production requirements arrive late: security reviews, data retention rules, scaling expectations. Prototypes get a free pass on these, but production doesn't. Instead of treating them as a checklist at the end, fold one or two production constraints into the prototype phase early. If the data layer can't handle real concurrency, find out while the code is still small and cheap to change. It's not about building a perfect system from day one; it's about letting the prototype fail on production's terms in a sandbox, not in a launch week firefight.
Finally, the runaround often lives in the approval chain, not the engineering. A prototype can move fast because it only has one stakeholder. Production has many, each with a veto. Shorten that chain by agreeing on a single decision-maker for good enough to ship and giving everyone else a defined review window. If feedback arrives after the window, it goes to the next iteration. That sounds blunt, but it converts endless consensus-seeking into a rhythm: build, ship, correct, repeat. Momentum is the scarcest resource in any transition, and protecting it is the real job.
Validation Proof You Can Show Your Own Engineers
When we say the system holds up under load, we don't expect you to take our word for it. The validation package includes raw benchmark outputs, the exact test harness we used, and a reproducible environment spec. Your engineers can rerun the same scenarios on their own hardware and compare numbers line by line.
Every claim in the spec maps to a specific test case with a commit hash and a timestamped log. There's no polished demo behind a curtain. If something fails, the failure output is included too, so your team can see where the edges are and what we did to address them.
We also include a differential testing report against the previous version, along with the scripts used to generate it. That means your engineers can audit the methodology, tweak parameters, and verify that the improvements aren't just artifacts of a favorable setup.
FAQ
Start with their track record in your specific fluid type, not just general industrial use. Ask for failure rate data from long-term deployments, not lab tests. A good sign is when they openly discuss sensor drift, temperature compensation, and false-positive rates instead of hiding behind vague reliability claims.
Request a sample unit and run it with your own fluid, tubing, and flow conditions. Pay attention to how the sensor behaves with air bubbles of different sizes and at varying speeds. Independent test reports from recognized labs add weight, but your own side-by-side comparison against your current sensor usually reveals more than any datasheet.
Confirm that all wetted materials meet USP Class VI, ISO 10993, or FDA food-contact requirements as needed. Look beyond the sensor body—ask about adhesives, coatings, and cable jackets. A manufacturer experienced in these industries will have documentation ready without you having to chase them for weeks.
Many buyers focus only on bubble size detection limits and forget about repeatability over temperature shifts, aging, or different tubing durometers. Also check how the sensor handles ambient light interference and whether it requires frequent recalibration. Low initial cost becomes meaningless if maintenance demands grow quickly.
Send them a realistic integration scenario, including space constraints, electrical interface needs, and expected volume. A capable partner will respond with specific questions about your application rather than a generic yes. If they offer to modify firmware, adjust housing geometry, or provide design support without large engineering fees, that is a strong positive signal.
Response time must be shorter than the time a problematic bubble spends in the sensing zone. If your fluid moves fast or bubbles are transient, a sensor rated for static conditions may miss them entirely. Ask for response time measured under your flow rate, not just the theoretical value, because real-world latency often includes signal processing and output switching delays.
Conclusion
Selecting a bubble sensor manufacturer isn't just about ticking boxes on a spec sheet—it's about finding a partner who understands that accuracy must endure beyond the demo bench. The best suppliers prove their sensors maintain zero-drift performance over years of continuous exposure to aggressive fluids, not just in a clean lab. They'll show you material compatibility charts backed by long-term immersion tests, so the sensor housing and sensing element don't degrade when faced with solvents, acids, or viscous media. False alarms are the silent killer of fluid detection systems; a reliable manufacturer tunes their sensing algorithms to distinguish a true bubble from turbulence, foam, or micro-debris, ensuring your machine never stops because of a phantom reading. And when your application demands a custom flow path or an exotic mounting geometry, they treat engineering as a conversation, not a form to fill out.
Beyond the initial samples, look for a partner who can scale without the runaround. Prototype-to-production should feel like a handoff, not a restart—same calibration, same test fixtures, same failure thresholds. Finally, demand validation proof your own engineers can scrutinize: raw data logs, test reports, and lifetime cycling curves. A manufacturer confident enough to hand over that evidence is one you can trust when the fluid gets messy and the line can't stop.
Contact Us
Contact Person: Ivy Zhang
Email: [email protected]
Tel/WhatsApp: +86 1081502288
Website: https://www.siansonic.com/